← Back to Projects
Machine LearningRecommendation SystemContent-Based Filtering

Goodreads-10k Book Recommendation System with Content-Based Filtering

Machine Learning — Recommendation System

Project Overview

This project builds a book recommendation system using Content-Based Filtering. Book metadata is transformed with TF-IDF and compared using Cosine Similarity so the system can recommend books with content characteristics similar to a selected title.

Tools Used

PythonPandasMatplotlibSeabornscikit-learnTF-IDFCosine Similarity

Dataset & Features

The project uses the Goodreads-10k dataset with 10,000 books and 23 columns. The recommendation content is constructed from title, authors, and original_title, while average_rating is used only as a heuristic relevance criterion during Precision@10 evaluation.

Machine Learning Workflow

Data Understanding → Missing Value Handling → Text Feature Combination → Text Normalization → TF-IDF Vectorization → Cosine Similarity → Top-N Recommendation → Precision@10 Evaluation

Recommendation & Evaluation Results

10K

The TF-IDF representation covers 10,000 books with up to 5,000 text features.

0.58

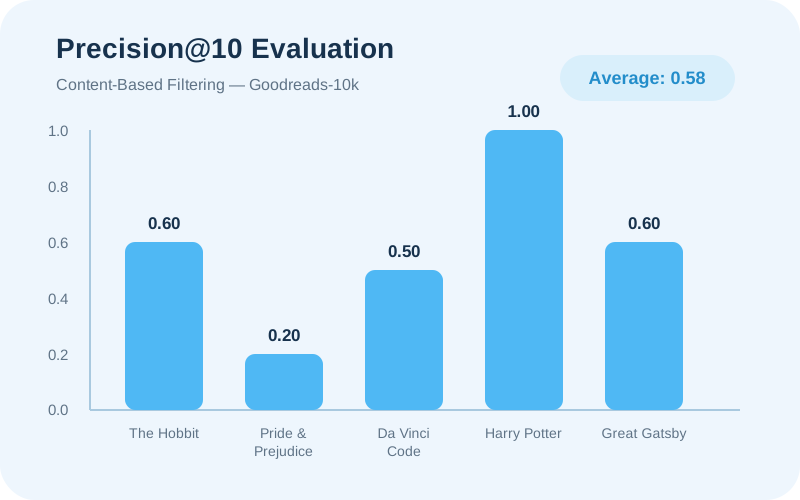
Average Precision@10 across five evaluated books is 0.58 using average_rating ≥ 4.0 as the relevance heuristic.

1.00

Harry Potter and the Sorcerer's Stone achieved Precision@10 of 1.00, meaning all 10 recommendations met the chosen relevance criterion.

CBF

The model can recommend books without requiring user-to-user interaction data because recommendations are based on item content.

Example Recommendations

01

For The Hobbit, recommendations include The Hobbit: Graphic Novel, The History of the Hobbit, The Silmarillion, The Children of Húrin, and other Middle-earth related titles.

02

For Pride and Prejudice, the model surfaces related retellings and Jane Austen titles such as Pride and Prejudice and Zombies, Eligible, Emma, and The Complete Novels.

03

For The Da Vinci Code, the recommendations include other Robert Langdon and code-related titles, including The Lost Symbol.

!

Because the model relies on title, author, and original title text, it may over-specialize and recommend items that are very similar rather than diverse.
Analysis & Evaluation Results

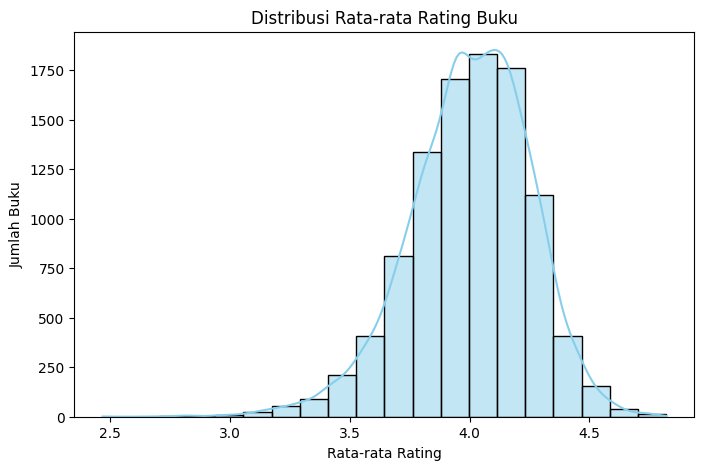
Distribution of average book ratings
Distribution of average ratings in the Goodreads-10k dataset
Precision at 10 evaluation for selected books
Precision@10 results for five evaluated books